Documentation describes the path. An SDK makes that path the default.
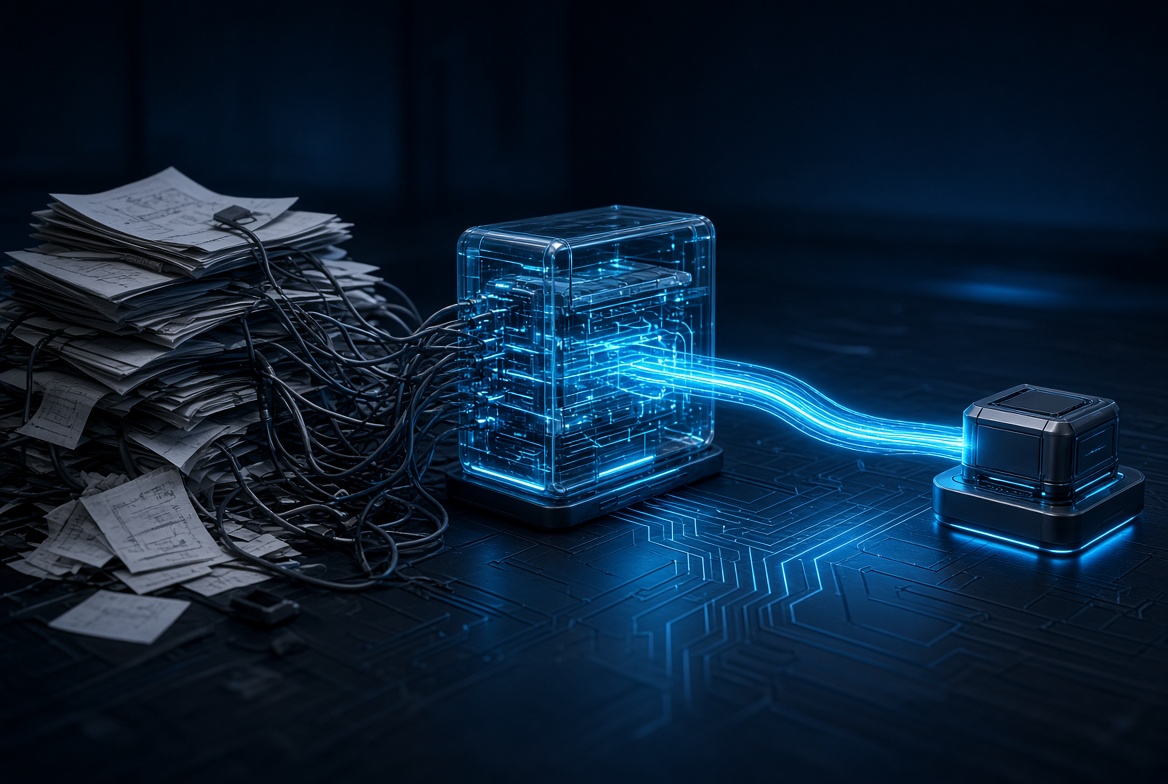
When a capability is more than a single API call, every consumer has to reconstruct the same sequence: look up a result, build the right key, deserialize, handle a miss, call the source, and decide what happens when the cache is down. You can write all of that down. Then every team still has to implement it.
An SDK is a package that hides that sequence behind a smaller interface. It can wrap APIs, auth, retries, config, serialization, and other details so the same capability is used the same way.
That matters most in a microservices system. Several independent services consume the same platform. Without a shared boundary, small differences spread: one service normalizes input differently, another forgets a version in the key, one fails hard when the store is down, another falls back. Documentation does not stop that. It still asks every consumer to understand and reproduce the same decisions.
Hide the integration
Without an SDK, a consumer might look like this:
const key = createResultKey("sales-report", 3, input);
const cachedResult = await resultStore.get(key);

if (cachedResult) {
  return JSON.parse(cachedResult);
}

return reportService.generate(input);
That is not hard once. It is hard ten times.
With an SDK, the consumer sees this:
const report = await reportClient.generateSalesReport(input);
The SDK looks up the result and falls back to the service when it must. The consumer does not need to know how keys are built or how fallback works. It only needs to generate a report.
Reuse is not the whole point
A shared helper can remove duplication. An SDK also defines the boundary through which teams talk to the capability.
For distributed memoization, that boundary can own:
- input normalization and key generation
- serialization and deserialization
- cache lookup
- timeouts and fallback rules
- connection and configuration
- authentication and authorization
If the key format changes from sales-report:v3:{input-hash} to result:sales-report:v4:{input-hash}, that is an implementation detail of memoization. It should not become an implementation detail of every service that uses it. The SDK is where that knowledge lives.
Make the expected path easy
Give ten teams docs on auth, retries, headers, error mapping, timeouts, and endpoint conventions, and you still get ten slightly different clients.
Or expose:
const client = new PlatformClient(config);
const result = await client.execute(input);
Docs still matter. Consumers should understand behavior and tradeoffs. They should not have to reproduce infrastructure code to use the platform correctly.
Standardization then depends less on memory. Auth changes in one place. New telemetry goes in one place. A timeout policy is one implementation, not several cousins across the codebase.
What belongs behind an SDK
Not every abstraction needs a package. A helper used twice is a helper.
An SDK is worth it when several consumers hit the same capability and that interaction has real rules. Internal APIs are the obvious case. The same idea applies to caching, auth, feature flags, event publishing, storage, and other shared platform work.
Draw the boundary at the concepts consumers care about. Keep infrastructure underneath.
An SDK that leaks every internal detail does not abstract much. An SDK that tries to cover every possible use case becomes harder than the system it hides. In the memoization example, the consumer cares about generating the report, not about turning a deterministic input into a cache key. That gap is the right place to draw the line.
Used there, an SDK is not just less copied code. It is an architectural decision implemented once, with an interface that is smaller and harder to misuse.
Reactions
Share this post
0 replies
Sign in with your Maxlayer account to join the conversation.