How to Get Frontier-Level Results From Cheap LLMs
I was scanning a large batch of code files for security issues. Claude 3 Opus was excellent — about 95% accuracy — but it cost roughly $1 per file. At hundreds of files, that adds up. I needed similar quality without the frontier-model bill.
The cheaper path was not “hope the small model is smart enough.” It was context engineering: treat the cheap model like a junior engineer with a runbook, not like an oracle.
Can a cheap LLM replace something like Claude 3 Opus?
For a narrow, well-specified task, yes — if you make up for fewer parameters with structure and guardrails.
Swap test: Opus → Nemotron.
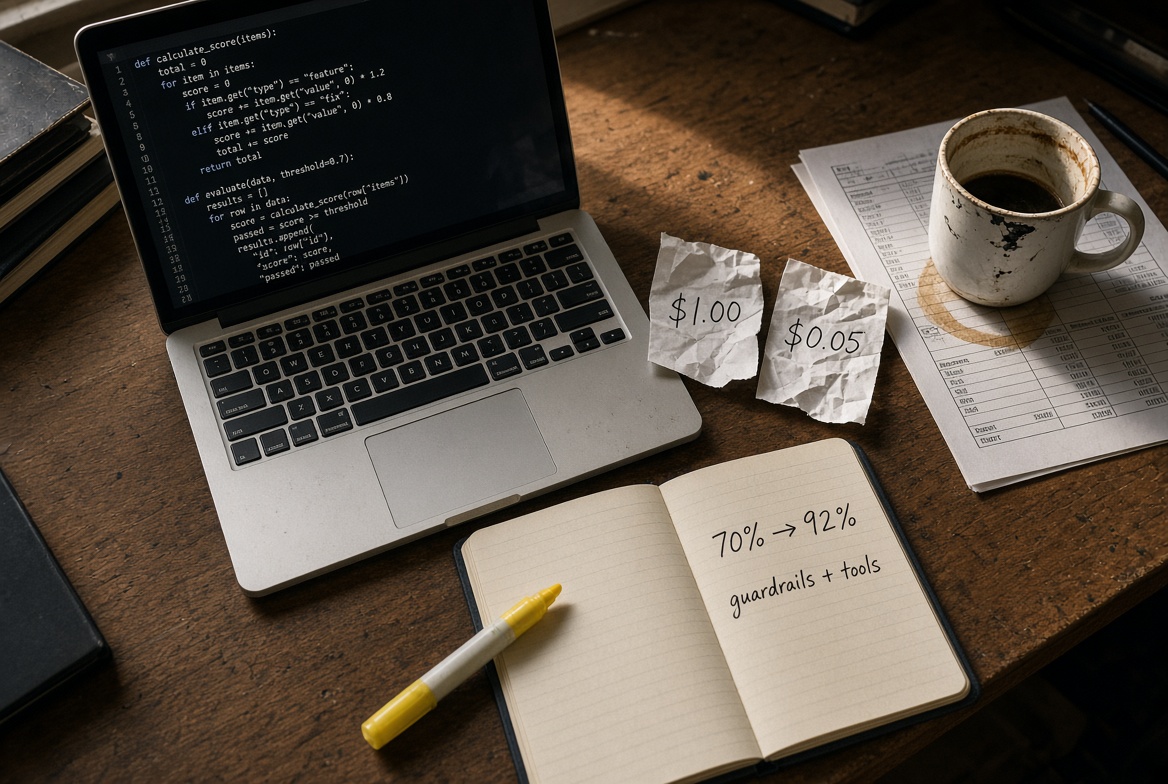
- Cost: ~$1.00 → ~$0.05 per file
- Raw accuracy: 95% → 70%
After adding guardrails, tools, and explicit examples of what a finding looks like, Nemotron reached 92%. Not quite Opus, but a 95% cost cut made it the production choice.
In that setup, a ~$0.05 model with structured guardrails closed the gap with a ~$1.00 model to within about 3%.
How to optimize a budget model
Don’t ask a small model to invent the whole reasoning process in one open-ended pass. Shrink the job:
- Tight system constraints
- A step-by-step evaluation rubric
- Targeted tools instead of “just look at the code”
That’s what moved Nemotron from “too sloppy” to “good enough to run at scale.”
| Configuration | Cost / file | Accuracy | Extra work |
|---|---|---|---|
| Claude 3 Opus, default | $1.00 | 95% | None |
| Nemotron, raw prompt | $0.05 | 70% | None |
| Nemotron + context & tools | $0.05 | 92% | Prompt design + validation schemas |
What actually raised accuracy
Three changes mattered most:
Strict schemas
Force structured JSON. Free-form text lets the model wander.Targeted tools
Don’t make the model guess whether a code pattern is valid. Parse first (linter output, regex helpers, AST-ish helpers), then analyze.Few-shot security patterns
Put clear true positives and false positives in the system prompt so the model has a concrete baseline for “this is a finding” vs “this is noise.”
Together, that cuts cognitive load. The model executes a procedure instead of inventing one.
FAQ
Does context-window size get in the way?
Often. Smaller models also get lost in long context. Chunk the input and only inject the reference material that matters. Don’t dump the whole repo into the prompt.
Is this cheaper than fine-tuning?
Usually yes. Prompt and context work needs no training run, no extra GPUs, and you can iterate in minutes. Fine-tuning is heavier and slower to change.
When should you still pay for a frontier model?
When the work is open-ended: creative synthesis, messy multi-step planning, or volume so low that engineering the cheap stack costs more than the API savings.
Takeaway: For repetitive, scoped tasks like security scanning, the win is not a bigger model. It’s a smaller model plus a runbook, examples, schema, and tools.
Reactions
Share this post
0 replies
Sign in with your Maxlayer account to join the conversation.